Generative AI in organizations and society
Climate-report retrieval benchmarks expose a knowledge gap for AI
ClimRetrieve measures whether search systems find the evidence a sustainability analyst needs in company climate reports.
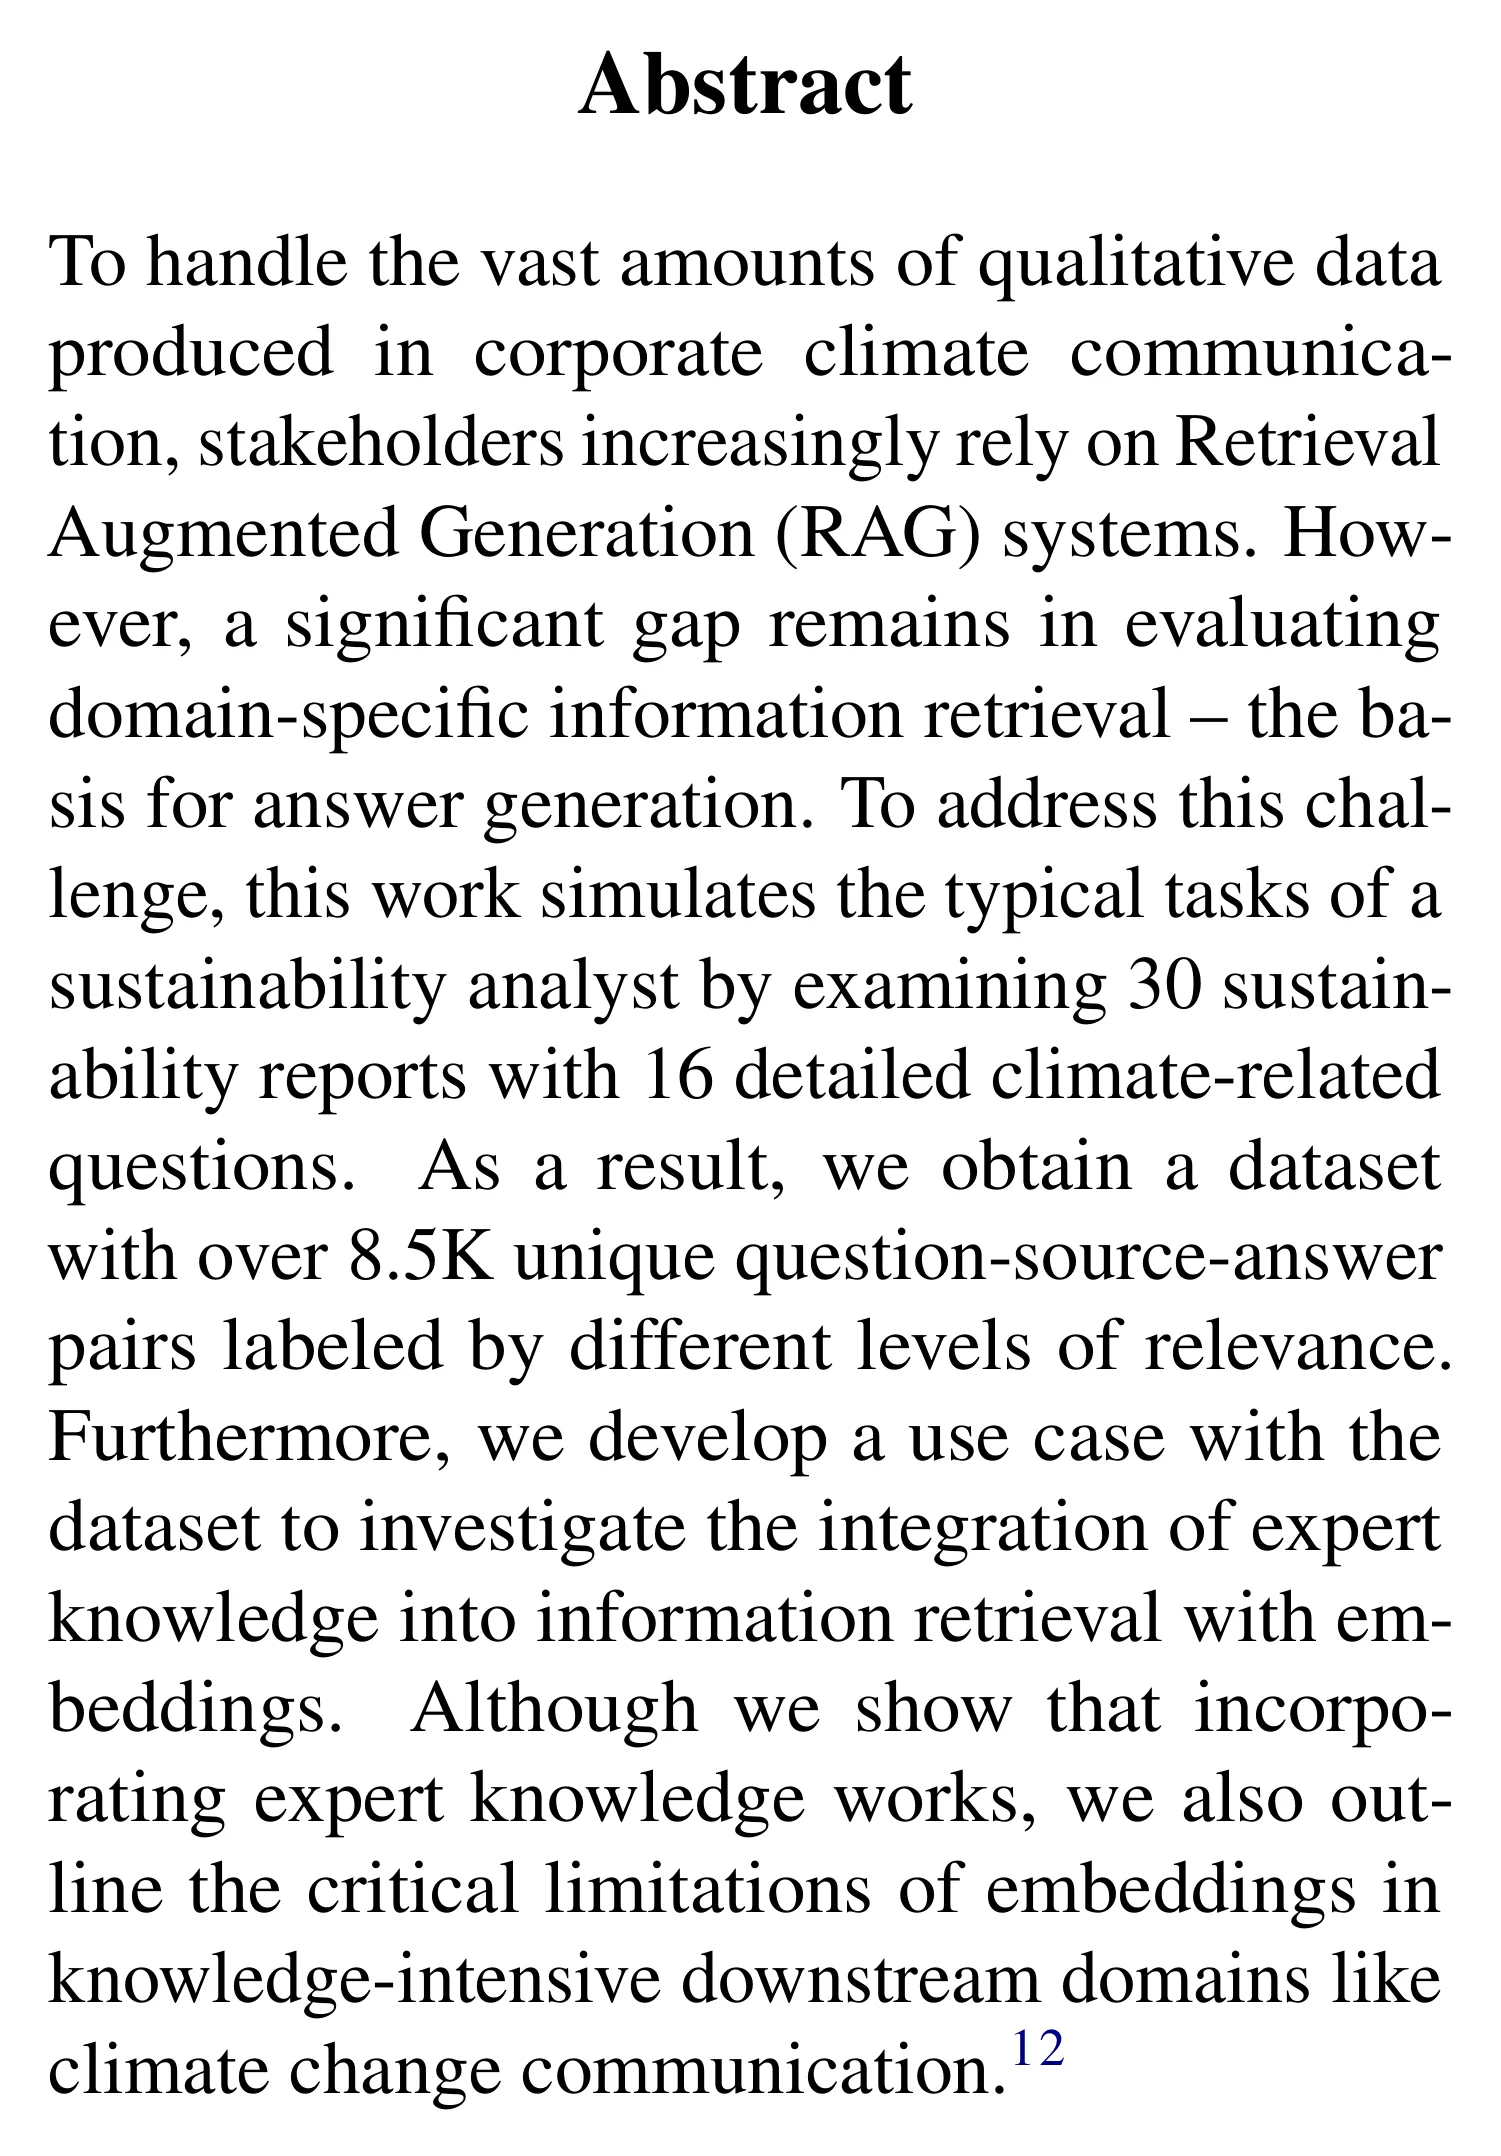
A language model can only answer a question about a climate report if its search step finds the right passage. ClimRetrieve focuses on that less visible stage: information retrieval from corporate sustainability disclosures, where relevant evidence is often qualitative and highly specific.
A dataset built around analyst questions
The authors examine 30 sustainability reports and 16 detailed climate-related questions. Their dataset contains more than 8,500 unique question–source–answer pairs. Each retrieved paragraph receives a relevance label on a four-point scale, from 0 to 3, so the data records degrees of usefulness rather than only a binary match. The benchmark also links a question to a report passage and an answer, reflecting the evidence chain an analyst needs (dataset design and Figure 1, PDF pp. 1–3; proceedings pp. 17509–17511). Each question–source pair therefore preserves distinctions that a simple correct/incorrect retrieval score would discard: a paragraph can be relevant without being the strongest evidence for an answer. This lets researchers examine ranking quality as well as whether useful evidence was found. The dataset is a test resource, not a complete catalogue of company disclosure language.
The questions cover information needs in climate disclosures, such as a company’s stated risks, plans or governance. The authors compare embedding-based search approaches, which represent text as numerical vectors and retrieve passages that are close to a query in that space. They also test whether expert knowledge can improve retrieval (methods, PDF pp. 4–7; proceedings pp. 17512–17515).
Domain knowledge helps, but matching meaning remains hard
The experiments show that adding expert knowledge can improve retrieval. At the same time, current embedding models do not reliably reproduce domain experts’ judgments about which passages matter. The paper’s central point is that good answer generation depends on a search system that understands the relevance of detailed climate language; simply retrieving text that sounds similar to a question may not be enough (results and embedding comparisons, Tables 1–2, PDF pp. 7–10; proceedings pp. 17515–17518).
That finding is about the tested reports, questions and retrieval configurations. It does not establish that every climate RAG system performs poorly, nor that expert annotations automatically transfer to a different company or reporting framework. The dataset is useful precisely because it makes retrieval quality measurable in a particular setting.
Scope and implications
The authors identify limitations tied to their expert workflow and dataset construction, including the finite set of reports and questions. Those choices shape which climate topics and relevance judgments appear in the benchmark (limitations, PDF pp. 13–14; proceedings pp. 17521–17522).
For organizations using AI to search disclosures, ClimRetrieve points to an evaluation question that can be overlooked: did the system surface the passage that supports its answer? The dataset gives researchers a way to test that stage directly and suggests that domain expertise may need to inform retrieval, not only the final response.
Bibliography & sources
- Tobias Schimanski, Jingwei Ni, Roberto Spacey Martín, Nicola Ranger, and Markus Leippold. “ClimRetrieve: A Benchmarking Dataset for Information Retrieval from Corporate Climate Disclosures.” In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 17509–17524 (2024). https://doi.org/10.18653/v1/2024.emnlp-main.969.