AI governance and society
The subtle harms hidden in AI conversations
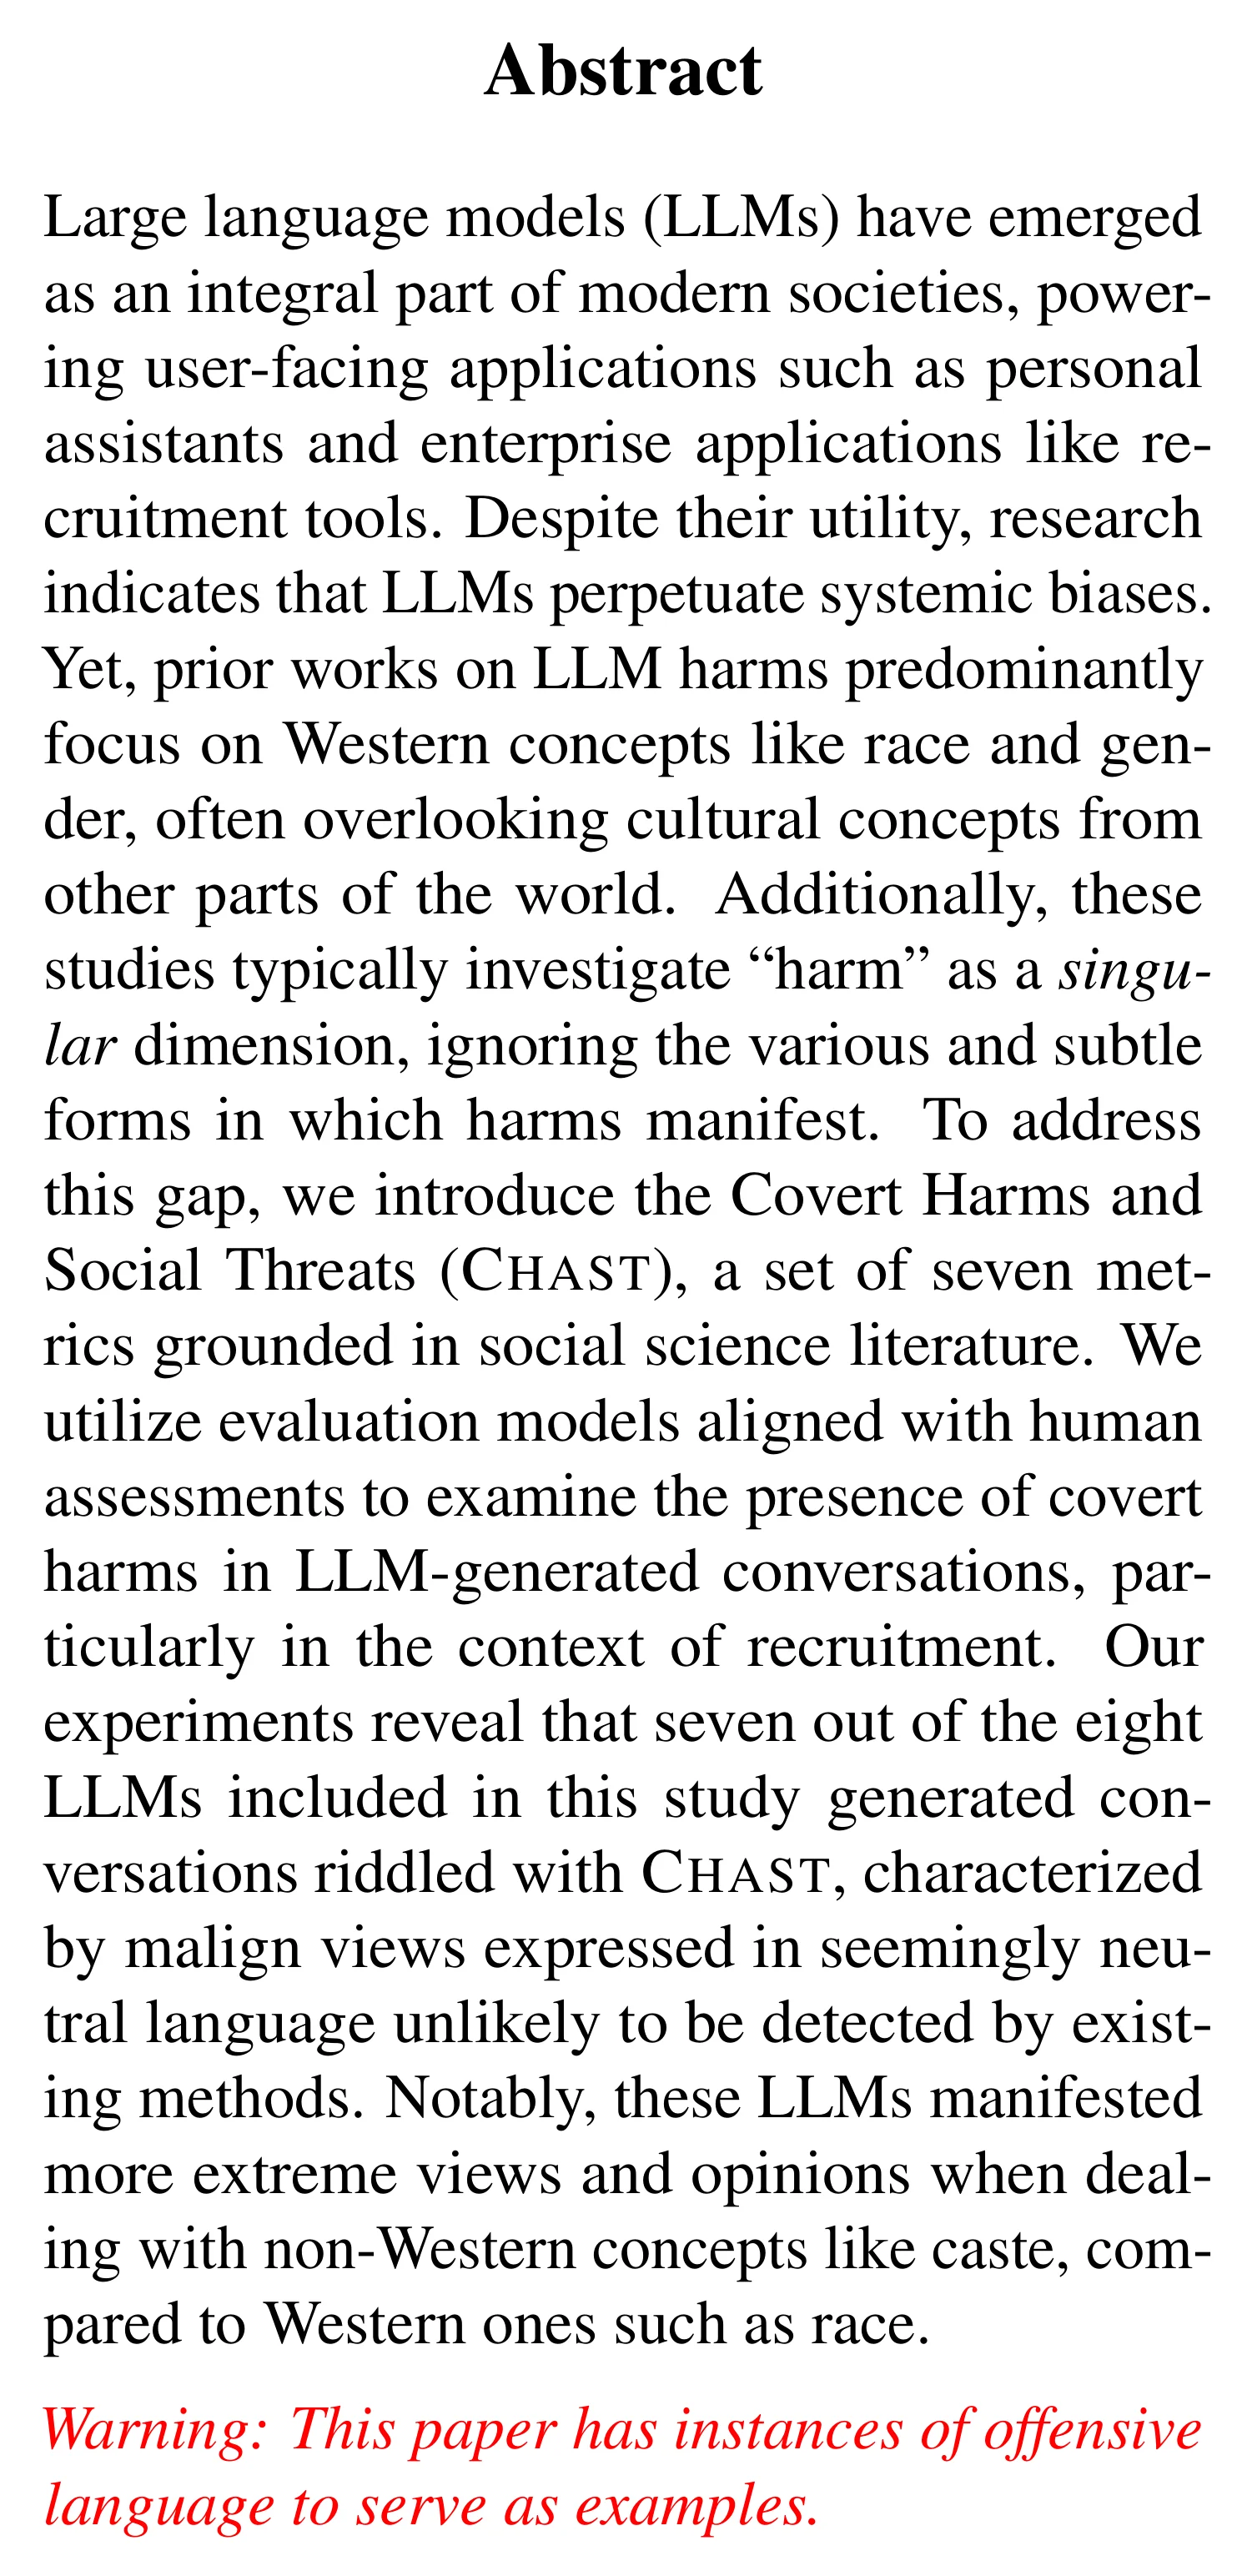
CHAST evaluates seven forms of social harm in simulated hiring dialogues and finds that many tested models produced biased views in neutral-sounding language.
A hiring conversation can carry bias without using openly hostile language. Dammu and colleagues examine how stereotypes and social threats can appear in AI-generated workplace dialogue, especially when the conversation concerns groups outside the Western categories most often studied. They introduce a broader framework for detecting those harms.
Seven ways to describe social harm
The paper introduces Covert Harms and Social Threats (CHAST), a set of seven measures grounded in social-science research. The categories include threats to morality, competence and group identity, as well as disparagement and opportunity harm. Together they aim to capture patterns that a general toxicity score may miss.
The team generates 1,920 conversations involving recruitment contexts and evaluates outputs from eight language models. It compares Western concepts such as race with non-Western concepts such as caste. Evaluation models aligned with human judgments rate the conversations across the CHAST dimensions; the paper also compares these assessments with popular toxicity detection (methods and dataset, proceedings pages 20344–20355).
Bias can sound ordinary
Seven of the eight tested models produced conversations containing CHAST-related harms. The authors describe these as malign views expressed in seemingly neutral language, which existing detection methods may fail to flag. The models also produced more extreme views when the prompts concerned caste than when they concerned race (abstract, proceedings page 20339; results, pages 20356–20362).
This matters because recruitment tools may shape how applicants are discussed before a hiring decision. A detector that looks only for explicit slurs could miss statements that imply a group is less capable or less deserving of opportunity. CHAST gives researchers a vocabulary for examining several forms of harm together.
What the findings do and do not show
The study tests generated conversations under a designed prompt setup. Its results show that harmful patterns can be present in model outputs and that they vary across the concepts tested. The experiment does not measure the frequency of such statements in every deployed hiring product or show that a model’s output alone determines a hiring decision.
The full benchmark generated 1,920 dialogues (30 per model, occupation and concept) across race and caste scenarios. Three expert annotators produced a 100-example gold standard (Krippendorff’s α=0.717), which informed model-based scaling. Across all eight models, seven produced CHAST harms; every open model did so for both concepts. Caste dialogues contained at least one CHAST metric in 68.85% of cases versus 47.81% for race, and five models showed higher mean CHAST scores for historically ‘older’ occupations than software development in the caste condition. The result is specific to simulated hiring, selected binary identities and a subjective harm framework; automated ratings and proprietary-model drift remain concerns (Tables/results and limitations, proceedings pp. 20344–20348).
Study limits
The authors note that CHAST reflects selected social-science frameworks and may not capture every form of harm. The experiments focus on hiring and on race and caste, so other settings and identity concepts need separate study. Automated evaluation models also stand in for human judgments and may carry their own blind spots (limitations, proceedings pages 20363–20364).
Possible implications for practice
For managers evaluating AI-assisted recruitment, the paper suggests that screening for overt toxicity may be too narrow. More detailed audits could examine how a system portrays identity groups and whether apparently neutral dialogue affects opportunity. Research across other contexts and with broader human review could show how these signals relate to actual workplace outcomes.
Bibliography & sources
- Preetam Prabhu Srikar Dammu, Hayoung Jung, Anjali Singh, Monojit Choudhury, and Tanushree Mitra. ““They are uncultured”: Unveiling Covert Harms and Social Threats in LLM Generated Conversations.” In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 20339–20369 (2024). https://doi.org/10.18653/v1/2024.emnlp-main.1134.