Generative AI in organizations and society
Code feedback helps LLMs query complex health records
EHRAgent uses generated code, medical context and execution feedback to answer multi-table questions in three electronic health record datasets.
Electronic health records store patient information across many linked tables. A clinical question may require locating a diagnosis, connecting it to a hospital stay and then calculating a cost. EHRAgent explores whether a language model can write and run code to carry out those steps instead of relying on a person to translate each request into database queries.
A plan that can be executed and corrected
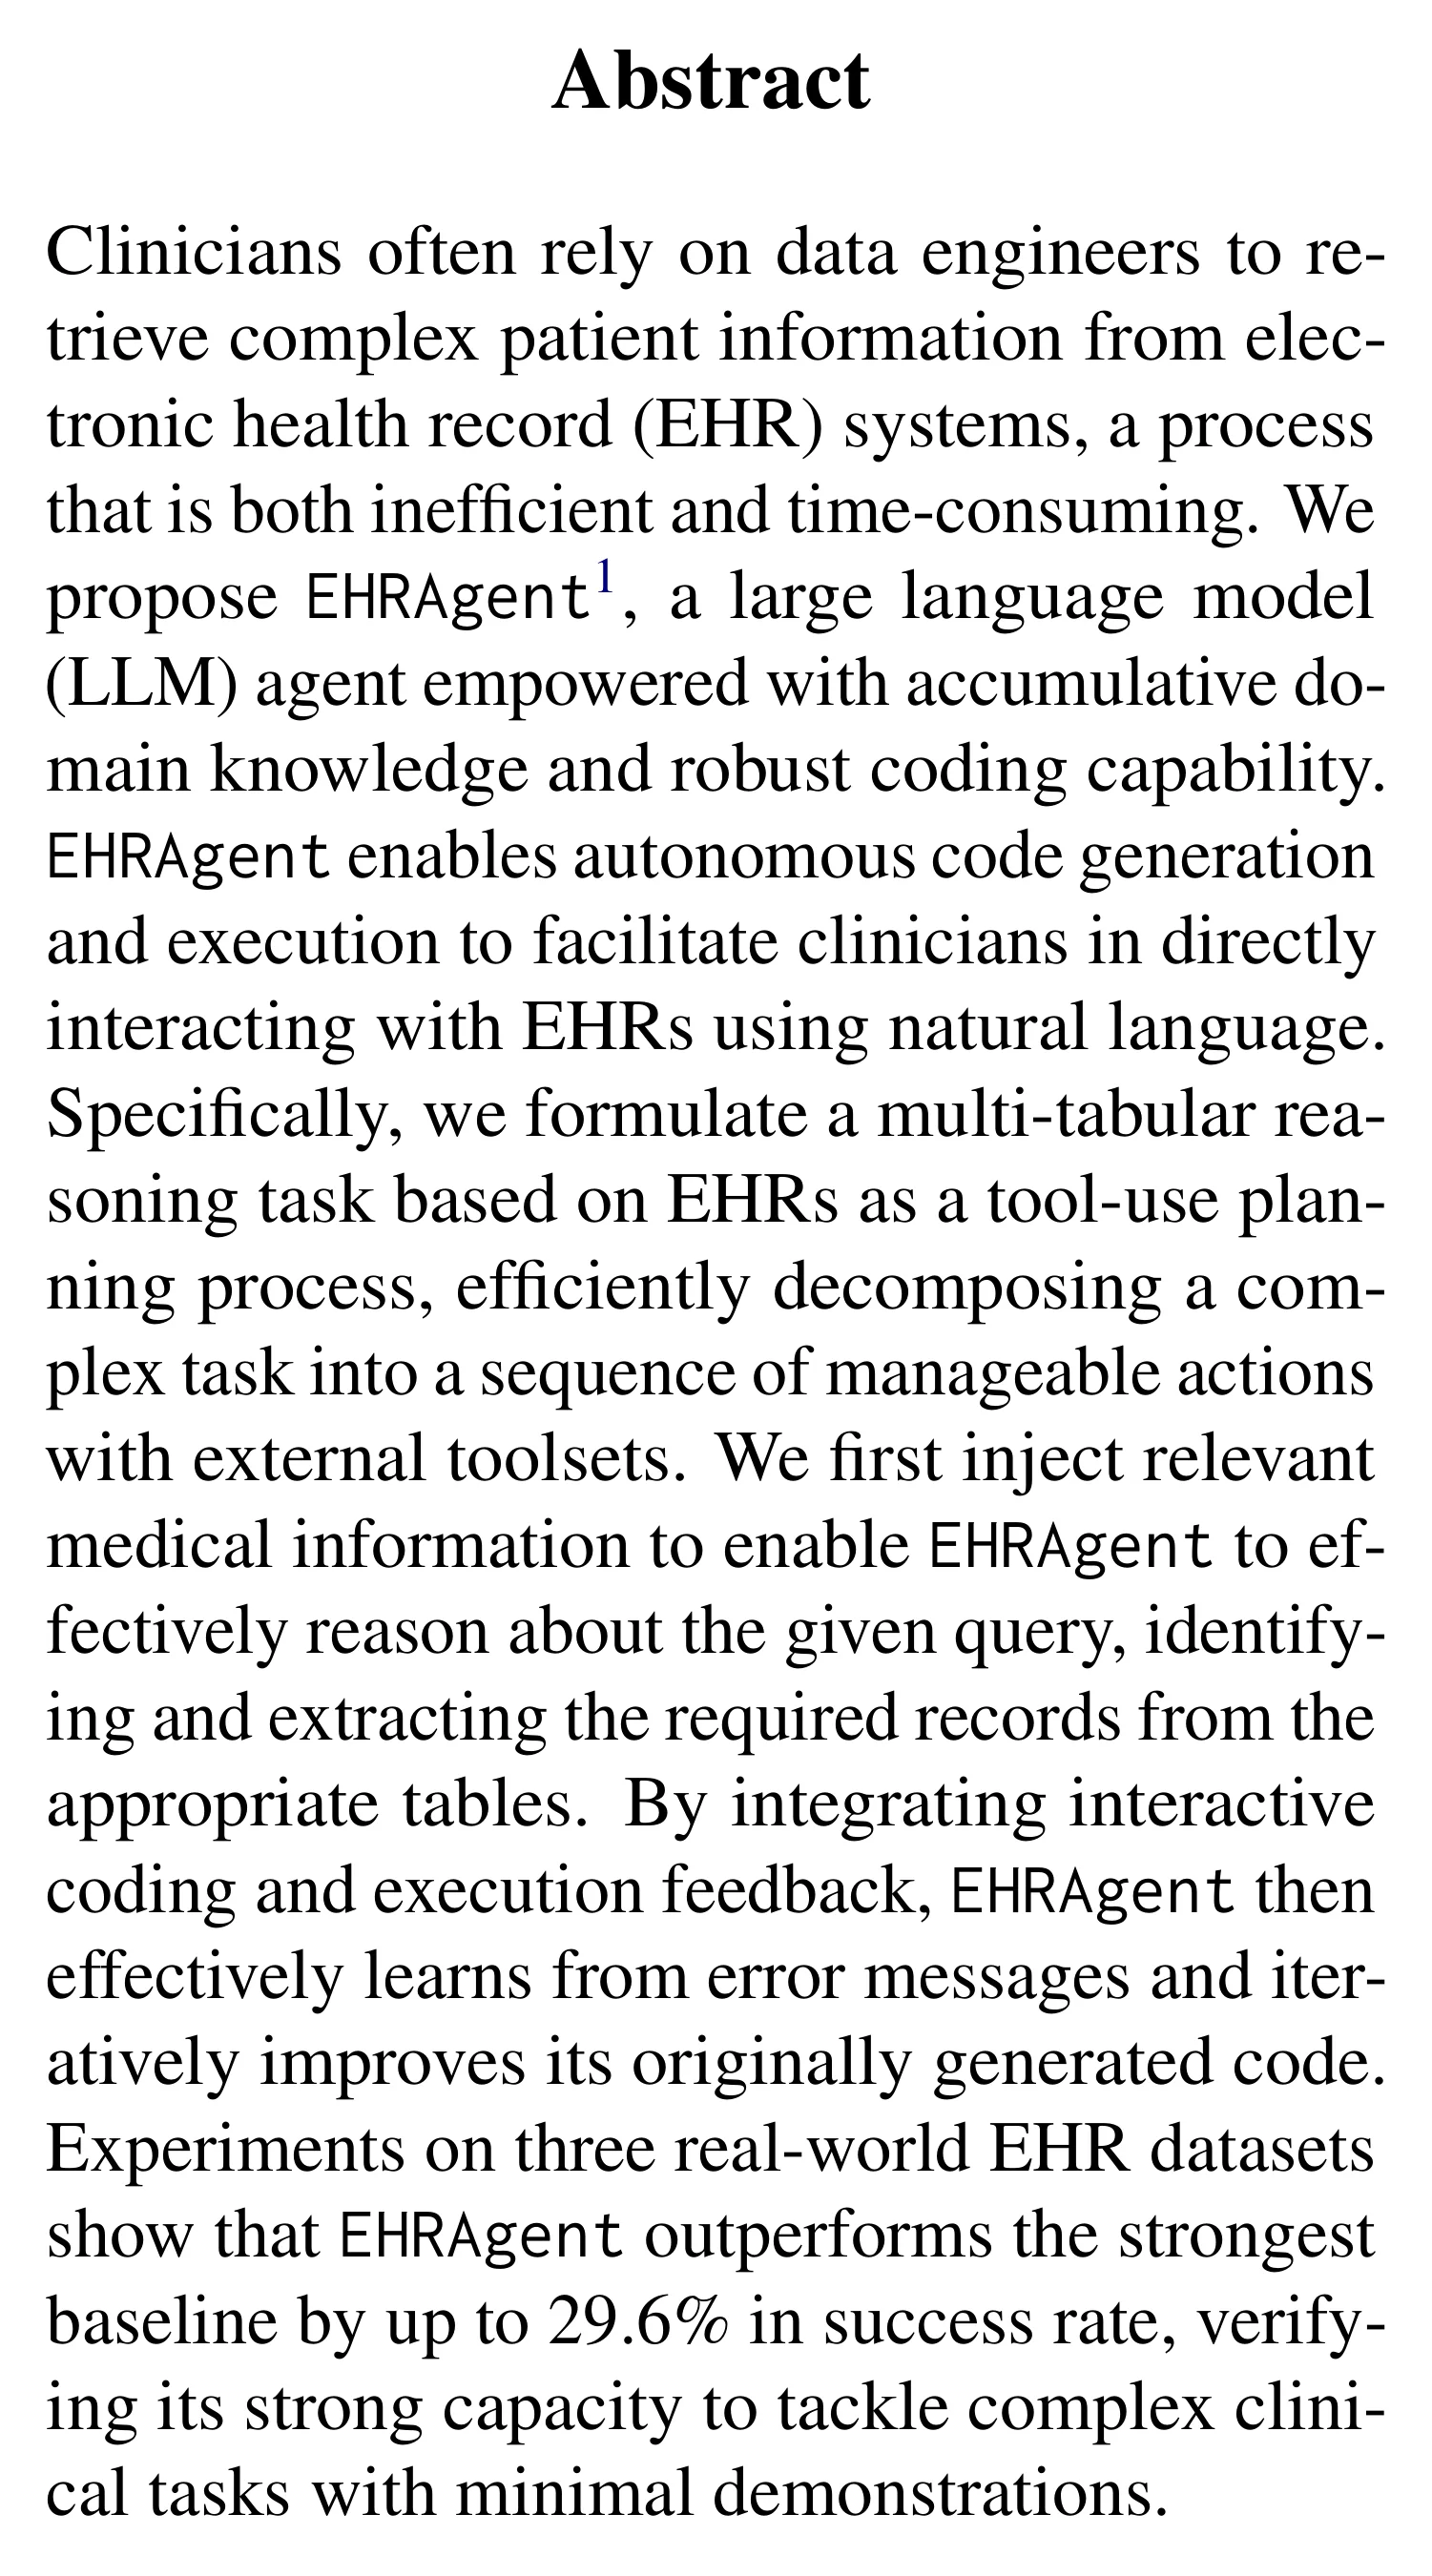
EHRAgent treats a question as a tool-use planning task. It first uses medical information to identify relevant tables and records. It then generates code, runs it through an interface and revises the code when execution returns an error. A long-term memory stores successful cases and selects relevant examples for new questions. The method is tested on MIMIC-III, eICU and TREQS, datasets that require reasoning over multiple tables (system design and task description, PDF pp. 1–4; proceedings pp. 22315–22318).
The authors use only four demonstrations in their few-shot setup. “Few-shot” means the model receives a small number of examples in the prompt or memory rather than being trained on thousands of labeled queries. Interactive feedback is important: an error message can tell the agent that its code refers to the wrong field or applies an invalid operation, giving it another chance to correct the plan (methods, PDF pp. 4–7; proceedings pp. 22318–22321).
Higher success on the tested multi-hop tasks
Across the three EHR datasets, EHRAgent improves on the strongest reported baseline by up to 29.6% in success rate. The paper distinguishes success rate from completion rate: success asks whether the final answer is correct, while completion records whether a system returned an answer. Table 1 reports the main comparison; later analyses examine performance under different task and context conditions (results, PDF pp. 8–11; proceedings pp. 22322–22325).
The finding is about benchmark questions and the tool environment used in the experiments. It does not show that the agent can safely retrieve patient data or make clinical decisions in a live care setting. The paper evaluates reasoning and query execution, not patient outcomes.
Limits and possible implications
The authors report that some difficult cases remain constrained by the information available in the model’s context and by the complexity of EHR structures (analysis and limitations, PDF pp. 11–13; proceedings pp. 22325–22327). Results on three datasets cannot capture every hospital’s schema, access rules or data quality.
For organizations building interfaces to complex databases, EHRAgent illustrates how executable tools can make a model’s plan testable and how feedback can support repair. Whether such systems fit clinical workflows will depend on access controls, correctness checks and evaluation against each institution’s own data model.
Bibliography & sources
- Wenqi Shi, Ran Xu, Yuchen Zhuang, Yue Yu, Jieyu Zhang, Hang Wu, Yuanda Zhu, Joyce C. Ho, Carl Yang, and May D. Wang. “EHRAgent: Code Empowers Large Language Models for Few-shot Complex Tabular Reasoning on Electronic Health Records.” In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 22315–22339 (2024). https://doi.org/10.18653/v1/2024.emnlp-main.1245.