Generative AI reliability
Knowledge checks can help reduce AI errors
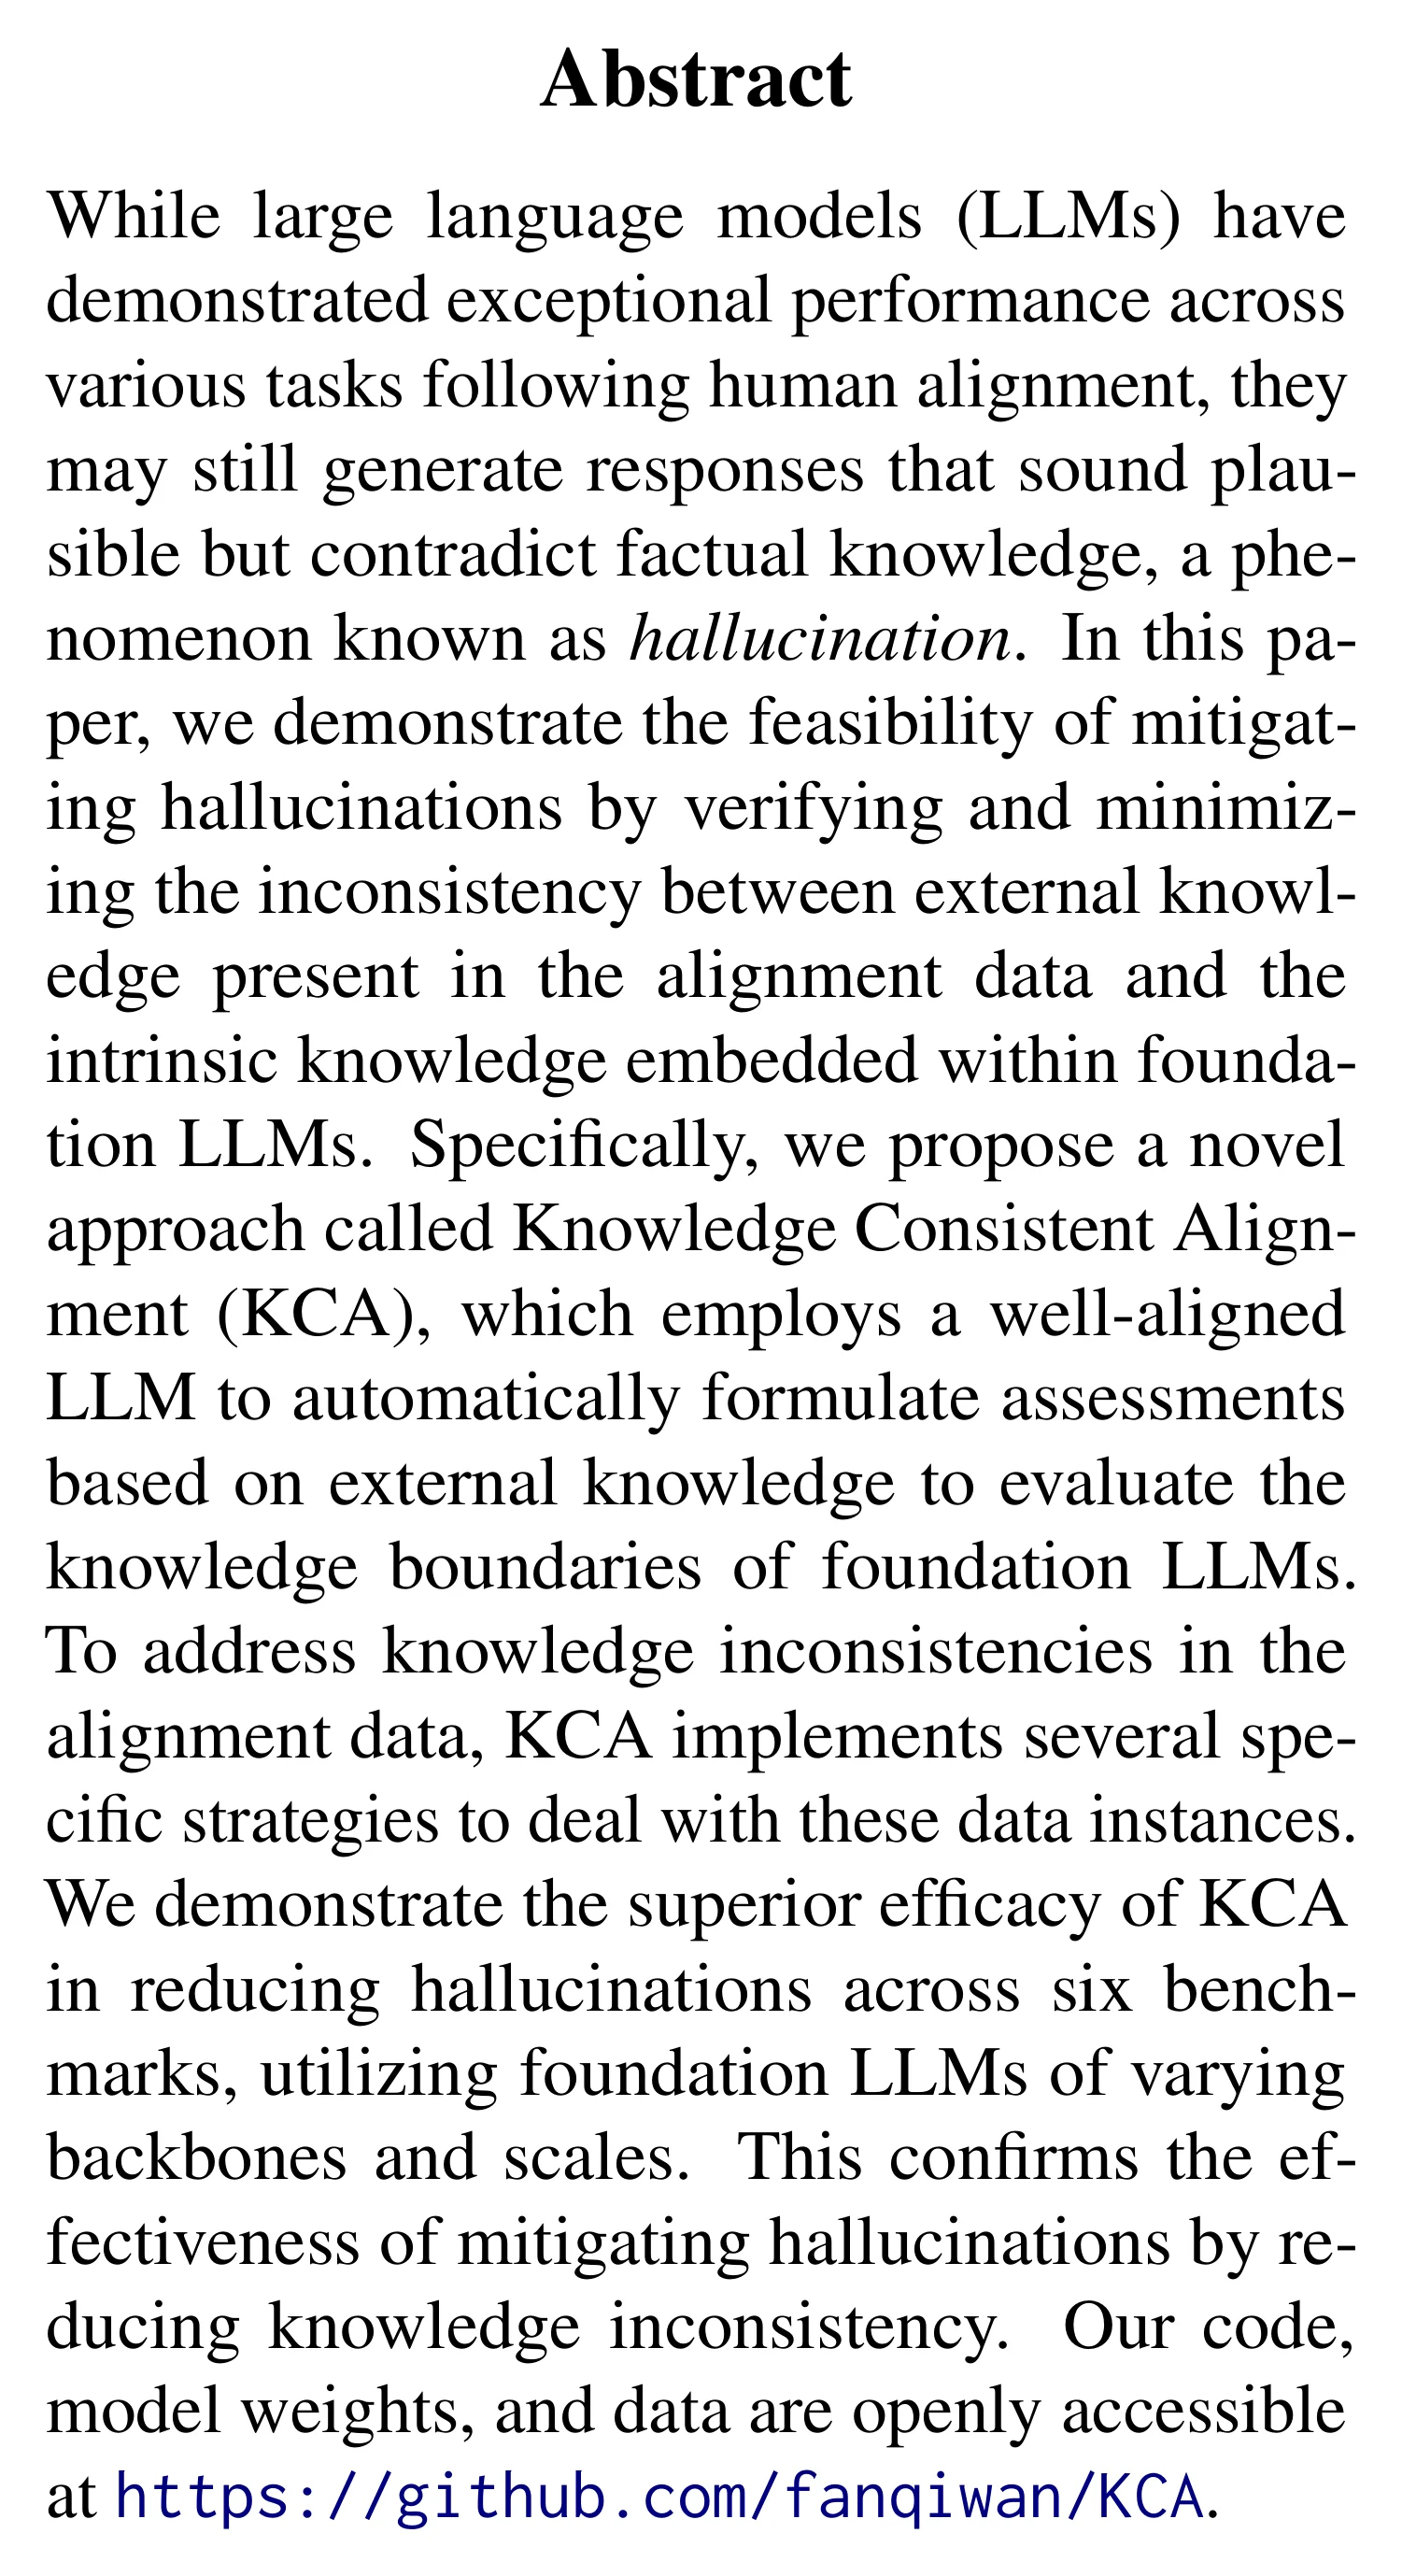
Knowledge Consistent Alignment tests what a model knows before fine-tuning and compares several ways to handle gaps.
Fine-tuning data can teach a model facts that its base version does not understand well. The authors of Knowledge Consistent Alignment (KCA) investigate whether those gaps matter for factual errors after alignment.
Test knowledge boundaries before training
KCA uses a well-aligned language model to generate questions about knowledge needed to answer each training instruction. The base model takes a multiple-choice assessment. Low scores flag examples that rely on external knowledge the model may not reliably know. The method then tests three ways to address those cases: provide reference knowledge with the question (open-book tuning), remove the example (discard tuning), or train a refusal response (refusal tuning).
The researchers evaluate several foundation models, including Pythia 7B, Mistral 7B, Llama 2 7B and Llama 2 13B, on six benchmarks spanning instruction following, truthful question answering, retrieval-augmented generation and clinical report generation. Table 1 (PDF p. 6) compares hallucination rates across models and tuning strategies. Its entries show that the strongest option varies by model and benchmark. The authors report that refusal tuning most often reduces hallucination, open-book tuning tends to preserve helpfulness, and discarding examples can balance the two outcomes (abstract and discussion, PDF pp. 2 and 6–8). Helpfulness measures are reported separately in Table 3 (PDF p. 8).
The method treats knowledge consistency as a data-curation issue. Rather than assuming every training response is safe to learn from, it asks whether the base model can demonstrate relevant knowledge before that example changes its behavior. This resembles an eligibility screen for alignment examples, backed by generated assessments.
Reliability depends on the training context
The experiments use specific datasets, model families and evaluation methods. Some tasks rely on language-model judgments; other tasks use overlap metrics such as ROUGE, which compare generated text with reference wording rather than directly checking factual truth. The authors discuss these distinctions in the methods and results (PDF pp. 5–8). The study does not show how the same approach would perform in a live training pipeline or with other kinds of organizational data.
Its results also expose a tradeoff. Refusal can lower observed errors by reducing the answers a model attempts, while open-book examples can give it extra evidence. These are different operating choices, and the paper measures task outcomes rather than their effect on user experience or service completion.
Possible implications for practice
KCA suggests that alignment quality may depend on whether training examples fit a model's existing knowledge. For teams evaluating fine-tuning, the results could motivate closer attention to what data assumes the model already understands. The study does not prescribe a single curation method; it shows that error and helpfulness outcomes differ across strategies.
Bibliography & sources
- Fanqi Wan; Xinting Huang; Leyang Cui; Xiaojun Quan; Wei Bi; Shuming Shi (2024). “Knowledge Verification to Nip Hallucination in the Bud.” Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, pp. 2616–2633. DOI: 10.18653/v1/2024.emnlp-main.152. Source paper